The Wider Lens logoThe Wider Lens

Today in AI

39 significant developments in the last 24 hours — Models: 2 · Open Source: 1 · Research: 3 · Tools: 10 · Agents: 1 · Robotics: 1 · Image & Video: 1 · Business: 16 · AI Hardware: 4

All stories →
The DecoderBusiness

Claude Fable 5.2 and Mythos 5.2 cement Anthropic's AI lead just before its IPO↗

Anthropic is releasing Claude Fable 5.2 and Mythos 5.2, its most powerful models to date, in two versions: one freely available and one reserved for verified organizations. The models solve open physics problems, show stronger cybersecurity capabilities, design functioning operating systems, and write more than 90 percent of the changes merged into Anthropic's core code, according to the company. Anthropic says it has deliberately curbed any capabilities that would let the AI accelerate its own development. The article Claude Fable 5.2 and Mythos 5.2 cement Anthropic's AI lead just before

MarkTechPostTools

Meta Releases Muse Ember, a 1M-Context Model for High-Volume Agent Work↗

Meta Muse Ember is Meta’s smallest model, built for tool calls, coding subtasks and document parsing. It ties Claude Haiku 5.5 on the Artificial Analysis Intelligence Index at roughly a third of the cost per task. The post Meta Releases Muse Ember, a 1M-Context Model for High-Volume Agent Work appeared first on MarkTechPost .

Trending / Important

  1. 1
  2. 2
  3. 3
  4. 4
  5. 5
  6. 6

Latest AI

View all →
The DecoderBusiness

Claude Fable 5.2 and Mythos 5.2 cement Anthropic's AI lead just before its IPO↗

Anthropic is releasing Claude Fable 5.2 and Mythos 5.2, its most powerful models to date, in two versions: one freely available and one reserved for verified organizations. The models solve open physics problems, show stronger cybersecurity capabilities, design functioning operating systems, and write more than 90 percent of the changes merged into Anthropic's core code, according to the company. Anthropic says it has deliberately curbed any capabilities that would let the AI accelerate its own development. The article Claude Fable 5.2 and Mythos 5.2 cement Anthropic's AI lead just before

OfficialRobotics

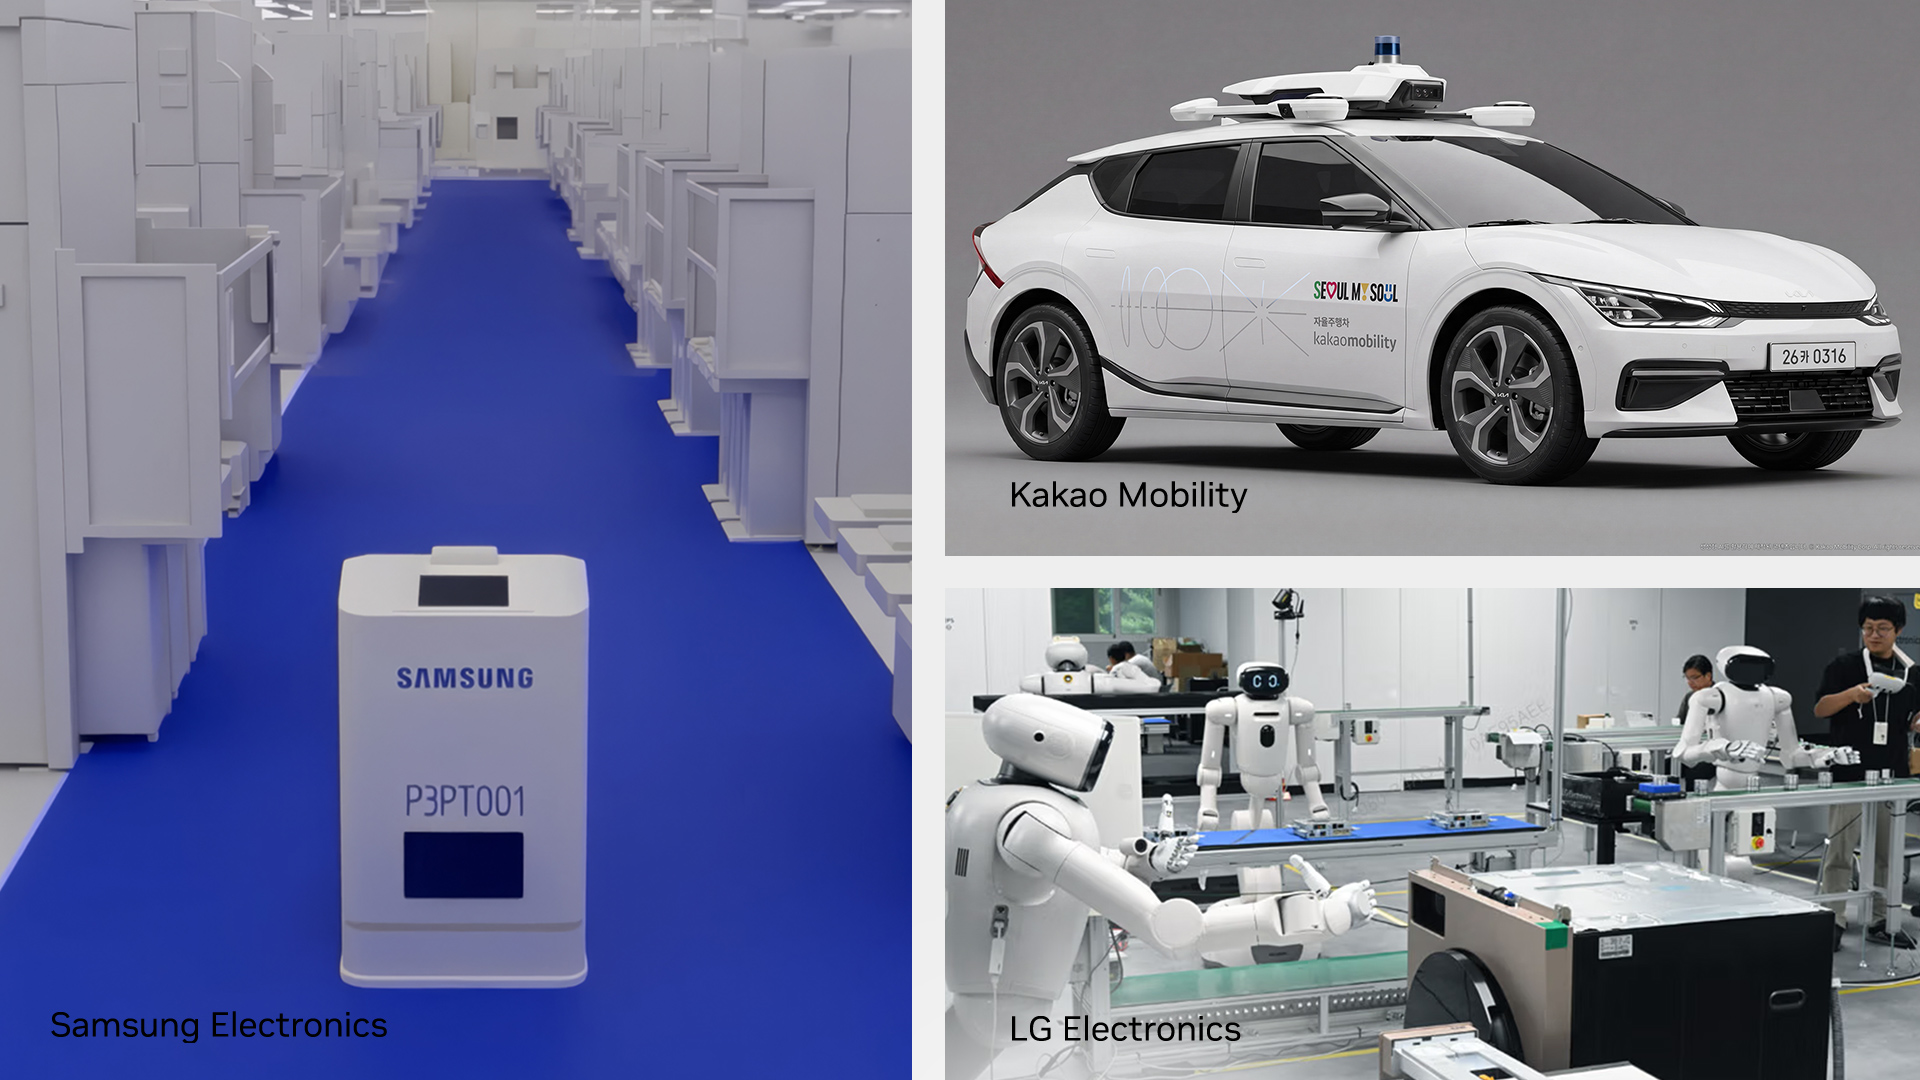
Korea Advances Physical AI Across Industries With NVIDIA↗

Tapping into the country’s strengths in manufacturing and engineering, NVIDIA is helping advance Korea’s physical AI ecosystem. The country’s industry leaders are applying accelerated computing, AI and simulation to everything from semiconductor manufacturing to robotics and autonomous vehicles. These efforts are helping bring physical AI from development into real-world production. Samsung Advances Semiconductor Engineering With […]

MarkTechPostTools

Meta Releases Muse Ember, a 1M-Context Model for High-Volume Agent Work↗

Meta Muse Ember is Meta’s smallest model, built for tool calls, coding subtasks and document parsing. It ties Claude Haiku 5.5 on the Artificial Analysis Intelligence Index at roughly a third of the cost per task. The post Meta Releases Muse Ember, a 1M-Context Model for High-Volume Agent Work appeared first on MarkTechPost .

OfficialResearch

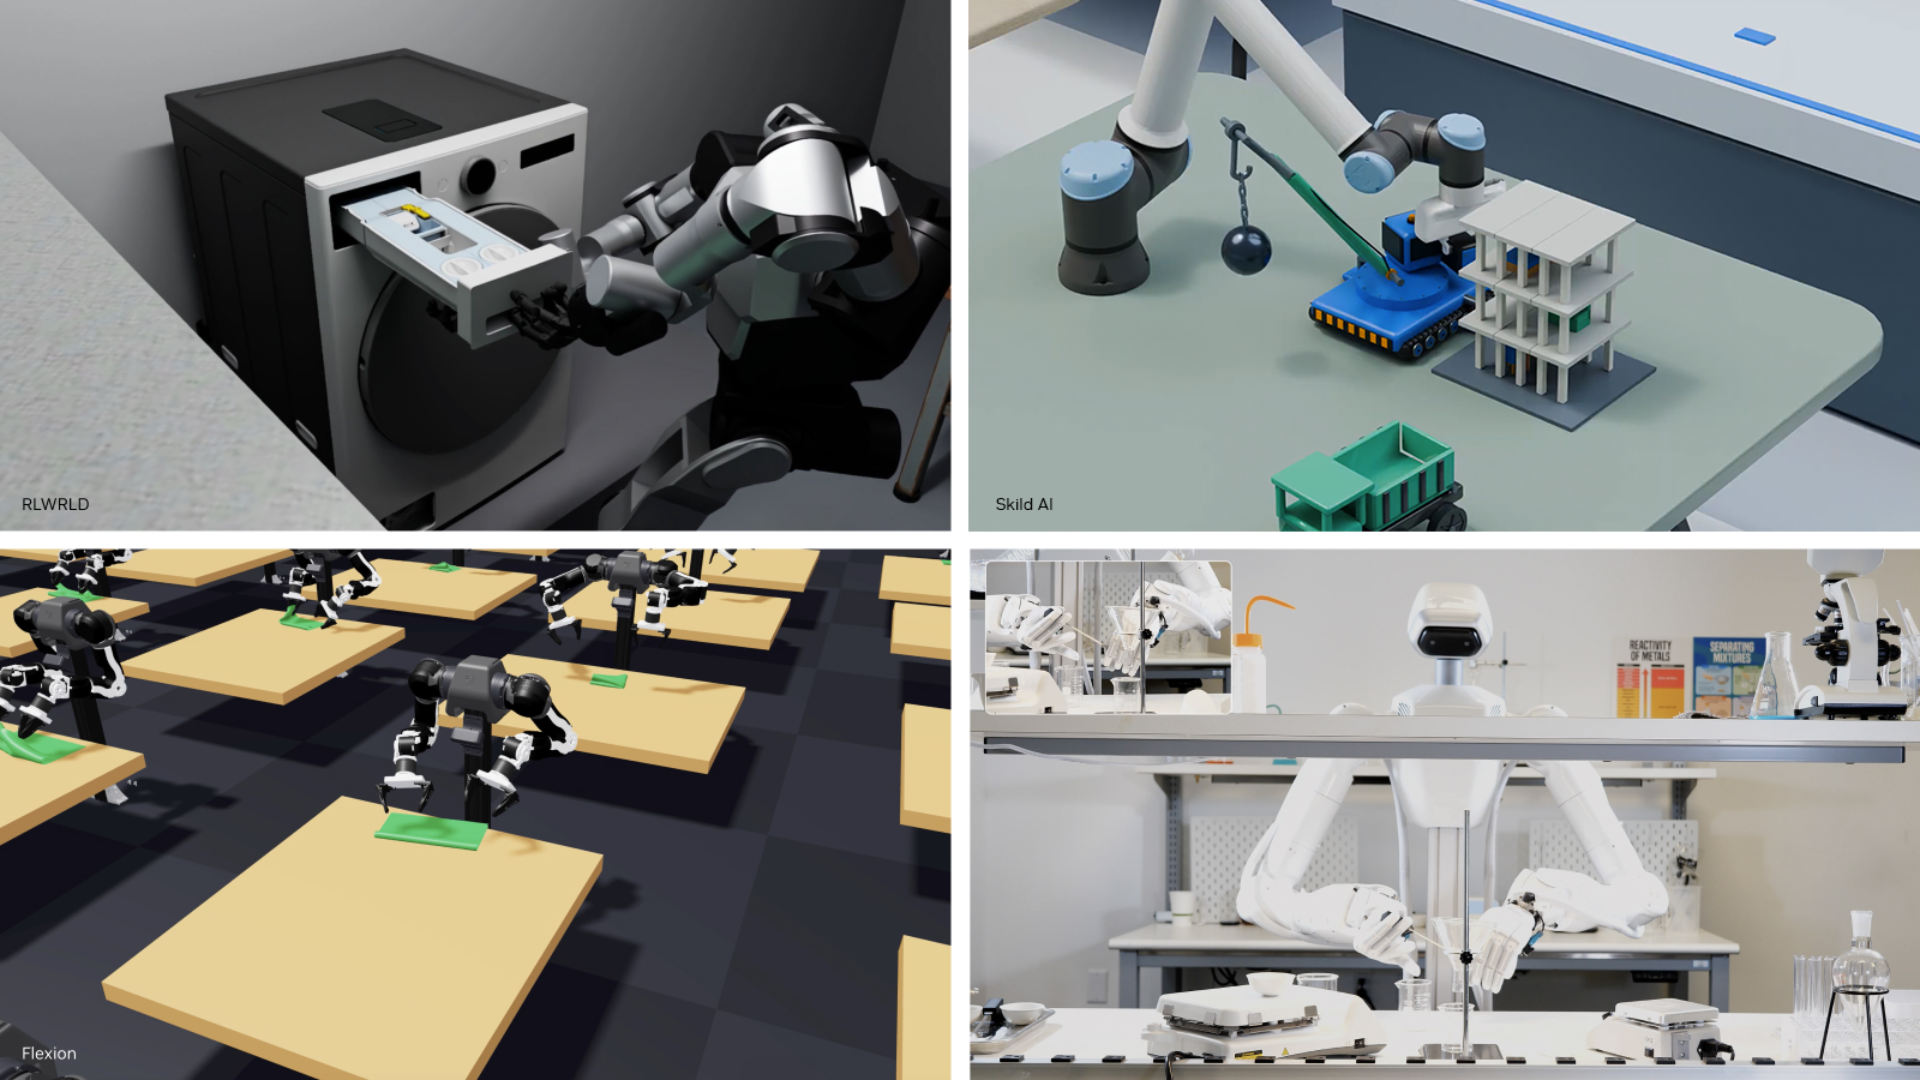
Practice Makes Precise: At CoRL, NVIDIA and Partners Reveal How Robots Rehearse Delicate Work in Simulation↗

Simulation, which has long been the proving ground for robots learning to walk, roll and hop, is now helping researchers teach robots tasks that require a finer touch: aligning gears, connecting cables and assembling small components. The shift from locomotion to manipulation is taking center stage at this week’s Conference on Robot Learning (CoRL) in […]

21h agoNVIDIA Blog
OfficialModels

NVIDIA Announces New Planned Investments in Korean Startups at the MSIT-NVIDIA AI Startup Partnership Forum↗

Korea’s Ministry of Science and ICT and NVIDIA hosted the MSIT-NVIDIA AI Startup Partnership Forum at COEX. Representatives from the Ministry of Science and ICT and NVIDIA met with over 20 Korean startups across foundation models, physical AI, AI infrastructure and AI semiconductors. NVIDIA also announced an investment in Korean startup Point2, with additional investments […]

1d agoNVIDIA Blog
The VergeAI Hardware

Everything we know so far about the Nvidia spy scandal targeting CEO Jensen Huang↗

The leather-jacketed CEO of Nvidia, Jensen Huang, has acknowledged an affair with Megaspeed exec Alice Huang, spurring an investigation by his company and intense discussions worldwide. Recent reporting noted that since last year, US intelligence reports had identified Alice Huang (no relation) as not only the exec for an AI compute company renting access to Nvidia GPUs, but also a spy for China’s Ministry of State Security. In recent years, Nvidia has become a key part of the Trump administration’s AI push, a central figure in negotiations over potential Chinese access to cutting-

New Models

Recently updated models on the Hugging Face Hub.

View all →

Latest Research

Recent AI papers from arXiv.

View all →
[object Object]

Reframe: Observation-Aligned Multi-Teacher On-Policy Distillation for Agentic Visual Reasoning↗

Agentic reinforcement learning (RL) and multi-teacher on-policy distillation (MOPD) offer complementary routes to post-training. For visual agents, however, tool use presents two related challenges. Models may overlook useful tool-returned observations, while poorly grounded actions can limit the evidence available for subsequent distillation. We introduce Reframe, a post-training framework that treats the observation state, rather than only the output distribution, as an object of alignment. First, Ground-Drop-GRPO (GD-GRPO) trains spatial and temporal specialists with evidence-aware rewards and stochastic removal of the original visual input, encouraging them to acquire grounded evidence and use the returned observations. Second, Observation-Gated-MOPD (OG-MOPD) replaces deficient tool actions with canonical ones mid-rollout and resumes distillation from the repaired observation. The t

16h agoHaozhi Yuan, Handong Li, Yifan Zhang et al.PDF↗
[object Object]

World In-Context Learning for Agentic Robot Manipulation↗

Trained action policies write manipulation skill into network weights, tying what is learned to the distribution it is learned from. In-context learning (ICL) avoids this coupling but has not matched trained policies, because a demonstration recorded in another scene carries no feedback from the world the robot currently faces. We observe that what an agent learns in context is semantic, recording task steps and object roles rather than visual appearance, so experience gathered in one world transfers to another. Based on this insight, we propose World In-Context Learning (WICL), a paradigm in which a frozen model starts from a demonstration, rehearses the task in a world such as a simulator, and writes the feedback into its context rather than its weights. We build RoboScript, a modular infrastructure that implements WICL for agentic manipulation. From a single demonstration, RoboScript

16h agoHeng Fang, Zehui Guo, Yuehan Zhang et al.PDF↗
[object Object]

Guiding Data Allocation for Robust Subpopulation Generalization↗

Machine learning models often achieve high average accuracy in the training data while performing poorly on test data due to subpopulation shift. A common data-centric solution is to enforce balanced subgroup proportions, but full balance can be costly, infeasible, and not always necessary. In this work, we study whether balanced training data is the unique optimal configuration for robust subpopulation generalization. We extend a Gaussian feature-model framework to theoretically characterize the performance landscape across general training subgroup distributions. We show that multiple configurations, including substantially imbalanced ones, can perform comparably to the balanced one. We further derive gradient-based directions for adjusting subgroup proportions to improve adjusted accuracy and worst-group accuracy more efficiently. These findings suggest that strategically allocating d

16h agoZhaoying Pan, Yipei Wang, Shenyu Lu et al.PDF↗
[object Object]

Beyond Modality Preference: Controlling Multimodal Arbitration under Modality Conflict in MLLMs↗

Multimodal large language models (MLLMs) integrate information across modalities, but become unreliable when those modalities disagree. Under conflicting inputs, MLLMs may favor modalities that are not the most reliable for the task, thus motivating inference-time control of modality arbitration. We identify a small set of attention heads, termed arbitration heads, that causally influence whether predictions follow visual or textual evidence. Building on this, we introduce a lightweight, training-free intervention that biases these heads toward a designated trusted modality at inference time. The identified heads are stable across calibration set sizes and generalize across settings, and steering them enables effective bidirectional control of modality reliance across diverse benchmarks. Our findings identify an effective control mechanism to align MLLM predictions with task-specified mo

16h agoZhaoying Pan, Shenyu Lu, Jun Hui Wong et al.PDF↗
[object Object]

Kolmogorov-Chapman Maps: Trajectory-Free Learning for Simulating Molecular Dynamics↗

Stochastic differential equations (SDEs) describe stochastic processes across a wide range of scientific domains, including physics, biology, and finance. Although individual numerical integration steps are inexpensive, observing meaningful events or transitions can require millions of sequential steps, resulting in substantial wall-clock simulation time and poor hardware utilization. Deep learning offers an alternative by amortizing many integration steps into a single neural network forward pass, potentially enabling much faster simulation. However, existing supervised approaches typically require long simulated trajectory data, which restricts their applicability. In this work, we introduce Kolmogorov-Chapman Maps (KC-Maps), a method for learning the transition kernel of an SDE that relies only on the trajectory-free marginal samples together with the known drift and diffusion coeffic

16h agoMajdi Hassan, Marta Skreta, Dominique Beaini et al.PDF↗
[object Object]

Grasping the Future: Joint 3D Hand-Object Forecasting From Internet Videos↗

To interact with an object, we need to anticipate both how it will move and how our hands should move with it. Human videos capture these relationships across everyday activities, offering a natural source for learning to predict future interactions. Learning from them requires recovering motion from completed interactions and using it to anticipate what could happen next. We present $\textit{Grasping-the-Future}$, a unified generative model of joint 3D hand-object motion, including wrist motion, finger articulation, and object position and orientation. Through masked spatiotemporal completion and flow matching, we train a single model for several prediction tasks: forecasting future interactions, predicting hand motion given object motion or vice versa, generating both trajectories toward a desired final object pose, and completing partially observed interactions. We explicitly model ha

16h agoRustin Soraki, Matthew Wallingford, Ryan Aby et al.PDF↗

Open Source Watch

Notable AI repositories and their latest releases.

View all →

affaan-m/ECC↗

The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.

★ 300.5k starsJavaScriptupdated 26m ago

Latest release: v2.2.3 (v2.2.3)↗

Tools & Agents

View all →
MarkTechPostTools

Meta Releases Muse Ember, a 1M-Context Model for High-Volume Agent Work↗

Meta Muse Ember is Meta’s smallest model, built for tool calls, coding subtasks and document parsing. It ties Claude Haiku 5.5 on the Artificial Analysis Intelligence Index at roughly a third of the cost per task. The post Meta Releases Muse Ember, a 1M-Context Model for High-Volume Agent Work appeared first on MarkTechPost .

5h agoMarkTechPostAsif Razzaq
The VergeTools

Seagate’s FireCuda Forge moves your data between a hard drive and SSD for better performance↗

Seagate announced a new external storage solution, called the FireCuda Forge, that combines the speed benefits of an SSD with the affordability of a higher-capacity hard drive. The Forge is the first drive that's powered by the company's new Alkemi intelligent storage platform, which learns how your data is used and relocates the files you're currently using, or use most frequently, to the faster SSD. The FireCuda Forge is now available through Seagate's online store with an 8TB hard drive for $699, or a 20TB hard drive for $899, that are both user-replaceable. However, the NVMe SSD is not inc

47m agoThe Verge
The VergeTools

Apple’s $50 Intelligence Usage Packs extend access to some AI features↗

After publishing a support article in early September outlining usage limits for some Apple Intelligence features, the company has updated Logic Pro with an option to "Buy More Usage" for a one-time purchase price of $49.99, as spotted by 9to5Mac . It has a built-in AI assistant to do things like "start a new song, set up a vocal track from a single prompt, or refine an active project." These Intelligence Usage Packs, as Apple calls them, will allow users to continue accessing certain Apple Intelligence features that have usage limits because they rely on cloud-based AI models from OpenAI or G

16h agoThe Verge

Browse

Categories

Companies

Links marked ↗ open the original source in a new tab. The Wider Lens shows headlines and excerpts only.